
Photo by author: Avoid the pitfalls of retraining your data
This complete guide to multi class neural networks will transform our data, create the model, evaluate with k-fold cross validation, compile and evaluate a model and save the model for later use. Later, we will reload the models to make predictions without the need to re-train.
Introduction
This is a multi-class classification problem, meaning that there are more than two classes to be predicted, in fact there are 7 categories.
- You can download the source code from GitHub
- If you would like to see how to code a neural network from scratch, check this article
- Download the dataset we will be using from Kaggle
- A very good article on multi class concepts which I reference below
This article will focus on:
- Import the classes and functions
- Train and save the model
- Load our data
- Prepare our features
- Split train and test data
- Hot Encoding Y
- Define The Neural Network Model
- Evaluate The Model with k-Fold Cross Validation
- Compile and evaluate model on training data
- Plot the learning curve
- Save the model
- Reload models from disk and predict
- Look at our files
- Reload the model
- Reload 5% random data
- Transform features
- Predict and check for accuracy
- Conclusion
1. Import Classes and functions
We can begin by importing all of the classes and functions we will need in this tutorial.
from keras.models import Sequential
from keras.layers import Dense
from keras.wrappers.scikit_learn import KerasClassifier
from keras.utils import np_utils
from sklearn.model_selection import cross_val_score
from sklearn.model_selection import KFold
from sklearn.preprocessing import LabelEncoder
from sklearn.pipeline import Pipeline
from sklearn.preprocessing import MinMaxScaler
from sklearn.model_selection import train_test_split
from joblib import dump, load
import pandas as pd
import numpy as np
2. Train and save model
2.1 Load our data
Lets load our data into a dataframe.
df = pd.read_csv('data/customertrain.csv')
df = df.dropna()
df = df.drop(['Segmentation','ID'], axis=1) # not needed
df.head()
Figure 1: Results of loading the data
We can see that we have 8068 training examples, but we do have some things to sort out:
- We will need to encode the categories from Y
- Use dump to save the encoder for later use
2.2 Prepare our features
We need to do a few things to our features, so we can work with them a little easier.
- Lets convert our string fields to numbers using OrdinalEncoder
- Use MinMaxScaler to normalise our numbers so thay have mean of zero with a deviation of 1.

Figure 3: Results after running column transformation
2.3 Split train and test data
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)2.4 Hot Encoding Y
The output variable contains seven different string values. When modeling multi-class classification problems using neural networks, it is good practice to reshape the output attribute from a vector that contains values for each class value to be a matrix with a boolean for each class value and whether or not a given instance has that class value or not.
This is called one hot encoding or creating dummy variables from a categorical variable.

Figure 4: Results of hot encoding Y
2.5 Define The Neural Network Model
So, now you are asking "What are reasonable numbers to set these to?"
- Input layer = set to the size of the features ie. 8
- Hidden layers = set to input_layer * 2 (ie. 16)
- Output layer = set to the size of the labels of Y. In our case, this is 7 categories
The network topology of this two-layer neural network can be summarized as:
8 inputs → [16 hidden nodes] → 7 outputs
2.6 Evaluate The Model with k-Fold Cross Validation
Now, lets evaluate the neural network model on all our data. We can evaluate our model on our dataset using a 10-fold cross-validation procedure.
After running, you should see a result of around 67.64%. Great, kfold has done its job, this is the best we can hope for from this dataset in terms of accuracy.
2.7 Compile and evaluate model on training data
Now, that we are happy with our epochs and batch size, lets compile a model we can use later.
2.8 Plot the learning curve
The plots are provided below. The history for the validation dataset is labeled test by convention as it is indeed a test dataset for the model. We can also see that the model has not yet over-learned the training dataset, showing comparable performance on both datasets.

Figure 5: Our learning curve is looking good. Could even reduce the epochs
2.9 Save the model
Now, lets save the model, so later we can reload and make predictions without the need to retrain. The model is then converted to JSON format and written to model.json in the local directory. The network weights are written to model.h5 in the local directory.
3. Reload models from disk and predict
3.1 Look at our files
The model and weight data is loaded from the saved files and a new model is created. It is important to compile the loaded model before it is used. This is so that predictions made using the model can use the appropriate efficient computation from the Keras backend.
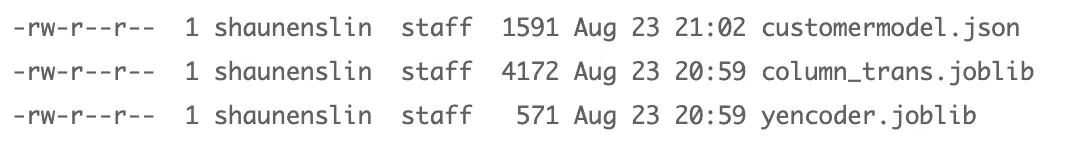
Figure 6: Saving our model, transformer and encoder
3.2 Reload the models
We will reload our data, simulating the event where we may be wanting to run a prediction a day or two later.
3.4 Reload 5% random data
Reload our training data, but take a 10% random sample.

Figure 7: Features before we transform

Figure 8: Features after we transform
3.6 Predict and check for accuracy
Reload our training data, but take a 10% random sample, you again should end up with an accuracy of 69%.
4. Conclusion
In this article you discovered how to develop and evaluate a neural network using the Keras Python library for deep learning.
You learned:
- How to load data and make it available to Keras.
- How to prepare multi-class classification data for modeling using one hot encoding.
- How to use Keras neural network models with scikit-learn.
- How to define a neural network using Keras for multi-class classification.
- How to evaluate a Keras neural network model using scikit-learn with k-fold cross validation
5. Sources
In this article I did find machinelearningmastery.com very helpful with alot of concepts easily explained.